Supply Chain Planning Software: How It's Built
Supply chain planning software decides what to make, buy, and stock before anything moves. Here's the planning hierarchy, the forecasting and inventory-optimization engines, the data model, and what it takes to build.
On this page
Supply chain planning software is the system that decides what to make, what to buy, and what to stock before a single pallet moves. It sits one level above the warehouses and trucks, working in forecasts and targets rather than scans and shipments. A demand forecast says how much you will sell. A supply plan says whether you can meet it. An inventory policy says how much buffer to hold so a late shipment or a sales spike does not turn into a stockout. Get that layer right and the rest of the operation runs on good numbers. Get it wrong and no amount of warehouse efficiency saves you, because you were building and buying the wrong things all along.
This guide is written from the builder's chair. Search the term and you mostly find vendor pages and "best supply chain planning software" listicles that wave at "AI and machine learning" without showing a single equation. We are going to do the opposite. This covers the planning hierarchy, the forecasting and inventory-optimization engines with the actual methods named, the data model underneath, the system architecture end to end, and an honest build-versus-buy framework. If you lead product or engineering at a company weighing whether to buy a planning suite or build one, this is the technical framing we use when we scope the work.
The short version
- Supply chain planning software decides what to make, buy, and stock before anything moves, working in forecasts and targets rather than the scans and shipments of execution.
- The discipline splits into four connected layers that feed each other: demand planning, supply planning, sales and operations planning (S&OP), and inventory optimization.
- The forecasting engine pairs classical statistical models like Holt-Winters and ARIMA with machine-learning methods such as gradient-boosted trees, then measures forecast error with MAPE or WMAPE.
- Supply planning is constraint-based optimization, usually linear or mixed-integer programming that respects factory capacity, supplier lead times, and minimum order quantities.
- Inventory optimization computes safety stock from a service level, demand variability, and lead-time variability, with multi-echelon optimization (MEIO) placing buffer across the network.
- The build-versus-buy call turns on one question: buy a packaged suite when your planning is standard, build or go hybrid when the planning logic is your competitive edge.
What supply chain planning software actually does
Supply chain planning software decides what to make, buy, and stock before anything moves, spanning four connected jobs: demand planning, supply planning, sales and operations planning, and inventory optimization. Demand planning forecasts what customers will want. Supply planning checks whether you can produce or source it against real constraints. Sales and operations planning reconciles those views with the financial plan into one agreed number. Inventory optimization sets the buffers that absorb the gap between the plan and reality. Together they answer one question continuously: given what we think will happen, what should we commit to right now. The category is large enough to have its own software market, with market-research estimates putting it in the low billions of dollars a year, though those figures vary widely depending on whether the analyst counts only planning suites or bundles in broader supply chain software, so treat any single number as a rough signal of scale rather than a hard fact.
The useful distinction to hold onto is planning versus execution. Planning sets intent. It works in future periods and writes targets. Execution runs the present: it picks orders, routes trucks, and moves stock through warehouses, which is the territory of the broader logistics management software stack. Planning is the brain, execution is the hands. The two talk constantly, the plan flows down into execution and the actuals flow back up, but they are different systems solving different problems. This article stays firmly on the planning side. We are not covering how to run a warehouse here, we are covering how to decide what belongs in it.
The planning hierarchy: demand, supply, S&OP and inventory
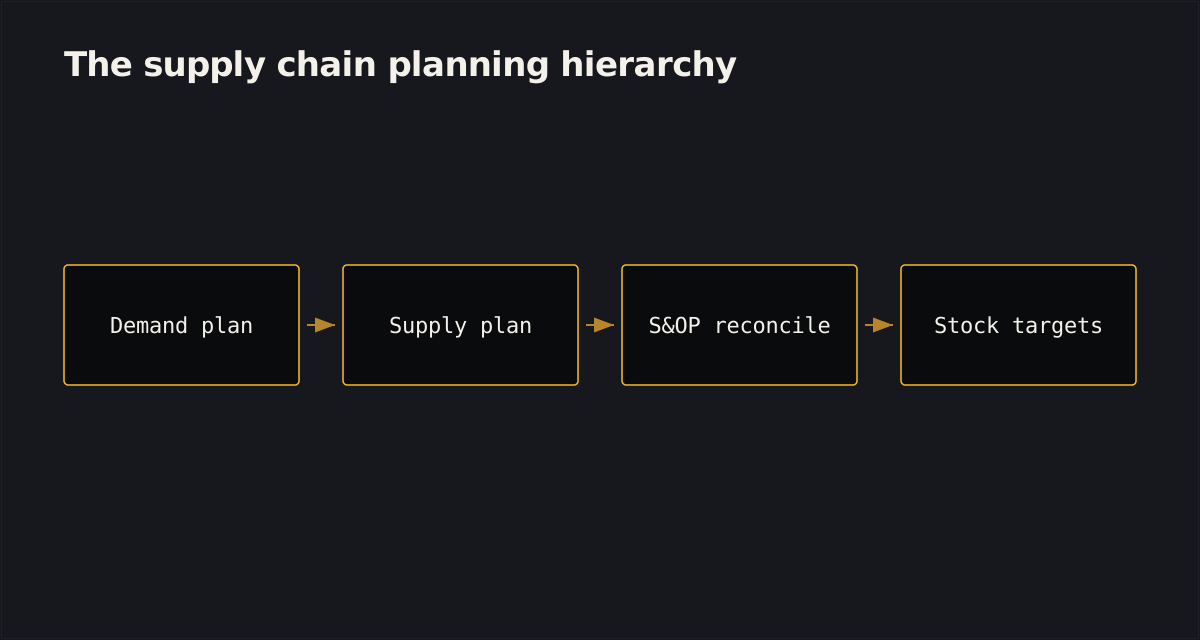
The planning hierarchy is the ordered pipeline where each layer feeds the next: demand plan to supply plan to sales-and-operations reconciliation to inventory targets. It is a hierarchy because the output of one stage is the input to the next, and skipping a stage breaks everything below it. You cannot plan supply without a demand number. You cannot reconcile in S&OP without both a demand and a supply view. You cannot set sane inventory targets without knowing the agreed plan and the forecast error around it. Order matters.
Walk it top to bottom. The demand plan produces a forecast of what customers will buy, by product, location, and period. That forecast becomes the input to supply planning, which tests it against factory capacity, supplier lead times, and material availability, then returns a plan that is actually feasible. Where demand and supply disagree, and they always do, S&OP is the reconciliation step that pulls sales, operations, and finance onto one set of numbers and forces a decision. The agreed plan, plus the measured uncertainty around the forecast, then drives inventory optimization, which sets the safety stock and reorder policies that protect service levels without drowning cash in excess stock. Each arrow in that chain is a place where software either keeps the data clean or lets it rot.
Inside the demand-forecasting engine: statistical methods vs ML
The demand-forecasting engine predicts future demand by product, location, and period, using two families of method: classical statistical models and machine learning. Demand planning software lives or dies on this engine, and the honest version of it is not one magic algorithm. It is a baseline you can trust, a more flexible model layered where the baseline struggles, and a ruthless habit of measuring the error so you know which one to believe.
Start with the statistical baseline, because it is cheap, interpretable, and surprisingly hard to beat on stable products. Exponential smoothing methods, including the ETS family and Holt-Winters, weight recent observations more heavily and decompose a series into level, trend, and seasonality. Holt-Winters specifically handles a product that is both trending and seasonal, which describes a huge share of real catalogs. ARIMA models the series through its own autocorrelation and works well when the history is long and reasonably regular. These methods are fast to fit across tens of thousands of items and they fail in understandable ways, which matters when a planner has to explain a number.
Machine learning earns its place where the statistical baseline runs out of road. Gradient-boosted tree models can ingest features a univariate method cannot see: price, promotions, weather, holidays, web traffic, the behavior of related products. They shine on demand sensing, where short-term signals sharpen the near-horizon forecast, and on long, irregular histories full of external drivers. The cost is interpretability and data hunger. A boosted model needs clean features and enough history to learn from, and it can overfit a promotion that will never repeat. The mature pattern is not religious. Run the statistical baseline everywhere, escalate to ML where the data justifies it, and let measured accuracy decide which forecast wins per segment.
Two more pieces make the engine production-grade. Forecasts are needed at many levels, the SKU, the product family, the region, the total, and those levels have to agree. Hierarchical reconciliation forces that consistency, so the sum of the child forecasts equals the parent rather than drifting. And none of it means anything unmeasured. Teams track error with MAPE and WMAPE, the volume-weighted variant that stops a tiny erratic item from dominating the score, and they watch bias to catch a model that consistently runs high or low. A forecast without an error metric beside it is a guess wearing a suit.
Supply planning and constraint-based optimization
Supply planning turns a demand plan into a feasible supply plan by testing it against real-world constraints: production capacity, supplier lead times, material availability, and minimum order quantities. The demand plan says what you want. Supply planning answers whether you can actually have it, and if not, what the best achievable plan looks like. This is a fundamentally different problem from forecasting. Forecasting is prediction. Supply planning is optimization under constraints, which is its own branch of engineering.
Frame it the way a solver does. You have an objective, usually some blend of meeting demand, minimizing cost, and keeping factories and suppliers within their limits. You have decision variables: how much to produce of each product in each period, how much to buy, where to hold it. And you have constraints that must hold no matter what: a plant cannot exceed its capacity, an order cannot arrive before its lead time, a supplier cannot ship below a minimum quantity. Constraint-based planning software encodes that as a model and searches for the plan that best satisfies the objective without violating a single hard constraint. Under the hood this is linear or mixed-integer programming, the same mathematical machinery that schedules airlines and routes power grids. The ERP-native version of this job, material requirements planning (MRP) and master production scheduling (MPS), nets a demand plan against bills of material and lead times without that optimization. The constraint-solving version described here is what vendors have long sold as advanced planning and scheduling, or APS.
The practical value shows up when something breaks. A key supplier slips two weeks. Capacity drops because a line goes down for maintenance. A solver-backed supply plan can re-balance across alternative sites, shift production between periods, and tell you exactly which orders are now at risk and which customers feel it first. That is the difference between a planning system that just records a problem and one that proposes a way through it. Building this layer is squarely a data-grade engineering job: clean constraint data, a model that mirrors how the business really runs, and performance that returns an answer in minutes rather than overnight. It is the kind of system work we do on custom logistics platforms, where the hard part is rarely the UI and almost always the correctness of the model underneath.
S&OP and IBP: turning many plans into one number
Sales and operations planning software supports the monthly cadence that reconciles the demand plan, the supply plan, and the financial plan into one agreed set of numbers. Without it, every function runs on its own spreadsheet: sales forecasts optimistically, operations plans conservatively, finance has a third figure in the board deck, and nobody is wrong on their own terms while the company is collectively flying blind. S&OP exists to end that. It is the formal process where the views collide on purpose and a single plan comes out the other side.
The framework here is well established. ASCM, the Association for Supply Chain Management, teaches the structured S&OP process and stewards the SCOR model that gives supply chain functions a common reference for how planning fits with source, make, and deliver. S&OP software automates the mechanical parts of that process so the meeting is about decisions, not data wrangling. It pulls demand, supply, and finance onto one shared dataset. It surfaces the gaps, the places where the supply plan cannot meet the demand plan or the plan misses the revenue target. It runs scenarios so the room can see the cost of each option before choosing. And it records what was decided, so the plan has an owner and an audit trail rather than evaporating when the meeting ends.
Integrated business planning, IBP, is the broader evolution of the same idea. Where classic S&OP centers on balancing volume against capacity, IBP pulls the financial plan and longer strategic horizons fully into the loop, so the operational plan and the money plan are the same plan rather than two documents reconciled after the fact. For a software build, IBP mostly raises the bar on integration and on scenario modeling: more data sources, tighter coupling to finance, and a real ability to play "what if" across the whole business. The hard engineering is not the meeting view. It is keeping every function honestly on one number between the meetings.
Inventory optimization: the math under safety stock
Inventory optimization software sets the stock buffers that protect service levels at the lowest viable cost, and it comes down to one formula: safety stock. Hold too little and you stock out, losing sales and trust. Hold too much and you bury cash in a warehouse and risk obsolescence. Safety stock is the calculated buffer that sits between those two failures, and the whole discipline is about computing it honestly rather than padding by gut feel.
The classic safety-stock formula ties three things together. You pick a target service level, the probability you want of not stocking out in a cycle, and convert it to a factor from the normal distribution, often written as Z. You measure demand variability, the standard deviation of demand over the lead time. And you account for lead-time variability, because a supplier whose delivery time swings wildly forces more buffer than one who is reliably slow. Combine them and safety stock rises with the service level you demand, with how erratic demand is, and with how unpredictable your suppliers are. That last term is why supplier reliability is an inventory lever, not just a procurement nicety. This is also exactly where the forecast error from the demand engine flows in: the demand variability the formula needs is the uncertainty the forecasting layer measured. The two engines are joined at the hip.
Service level is the dial that makes the trade-off explicit. Pushing from a 95 percent to a 99 percent service level does not cost a little more buffer, it costs disproportionately more, because the Z-factor climbs steeply in the tail of the distribution. Good software shows planners that curve so they can set service levels by product importance rather than applying one blanket target to a whole catalog.
The teams that win at planning treat it as an engineering and data problem, not a dashboard. The forecast is the easy demo. The reconciliation, the constraint model, and the safety-stock math that actually holds up under a late shipment are the build.
Two refinements separate a real system from a textbook example. ABC/XYZ segmentation classifies items on two axes at once: value or volume on the ABC axis, and demand predictability on the XYZ axis. A high-value, steady item gets a tight, confidently set policy. A low-value, erratic item gets a different rule entirely, because spending planner attention on it is waste. The second refinement is multi-echelon inventory optimization, MEIO. A naive system sets safety stock at every location independently and ends up holding the same buffer three times over across a network. MEIO optimizes stock across the whole echelon structure at once, the plant, the regional center, the local depot, positioning buffer where it protects service most efficiently instead of duplicating it everywhere. On a real network MEIO is often where the largest cash savings hide.
The planning data model
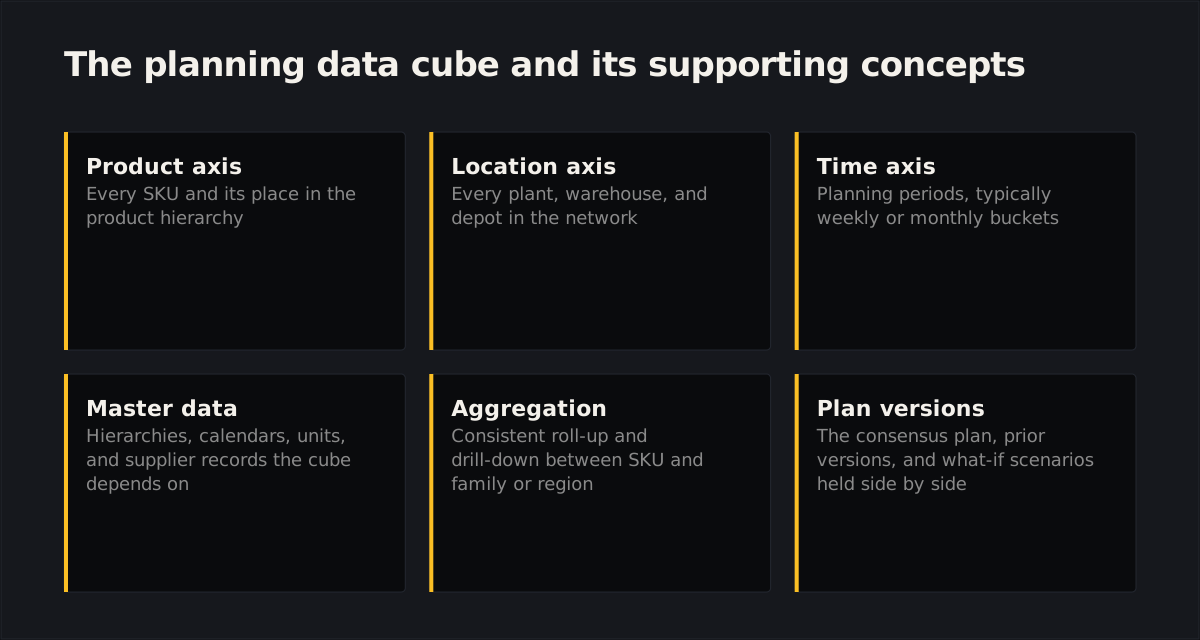
The planning data model is the structure that holds every plan, and at its heart is a three-dimensional cube: product by location by time. Every forecast number, every supply quantity, every inventory target lives in a cell addressed by which SKU, which location, and which time bucket. That sounds simple until you realize a real catalog has tens of thousands of SKUs, hundreds of locations, and a couple of years of weekly buckets, which multiplies into hundreds of millions of cells the engine has to read, write, and aggregate fast. Getting this model right is most of what makes a planning system quick or painfully slow.
Three concepts sit on top of the cube. Master data is the spine: the product hierarchy, the location network, the calendar, the units of measure, the supplier records. If master data is dirty, every number computed on top of it is dirty too, which is why data quality work is never optional on these builds. Aggregation is the second concept, the ability to roll a SKU-level forecast up to a family, a region, or a total and to push a top-down target back down to the SKUs, all while the numbers stay consistent. The third is plan versions and scenarios. A planning system is never working one plan. It holds the current consensus plan, the prior version to compare against, and a set of what-if scenarios a planner spins up to test a decision before committing. Treating versions as first-class data, rather than overwriting yesterday's numbers, is what lets a team reason about why the plan changed.
Integration: ERP, OMS and WMS as the data backbone
Integration is the work of connecting planning software to the transactional systems that own the real data, because a planning engine produces nothing useful without a clean feed of actuals. Planning sits on top. It reads from the systems of record, computes, and writes targets back down. The forecast is only as good as the sales history behind it, and the supply plan is only as good as the inventory and capacity data it runs on, so the integration layer is where a planning build quietly succeeds or fails.
Three systems form the backbone. The ERP is the system of record for sales history, master data, and financials, the raw material the forecasting and S&OP layers depend on. The warehouse management system holds the real inventory position, on-hand and in-transit, which the inventory math needs to be current rather than a day stale. The order management system carries open and committed orders, the demand signal that has already firmed up; our order management system guide goes deeper on that layer. Data moves in two directions. Actuals, stock, and orders flow in. The approved plan flows back out as replenishment signals, production schedules, and inventory targets that execution systems act on.
The timing of those feeds is a real design decision. Master data and sales history can run as a nightly batch, because the forecast does not change minute to minute. Inventory and order signals increasingly justify streaming closer to real time, especially for fast-moving products where a day-old stock position leads to a bad decision. There is a related but distinct discipline that often gets confused with planning here: real-time tracking of where goods physically are, which belongs to supply chain visibility software rather than the planning engine. Visibility tells you where the truck is. Planning decides what should have been on it. They feed each other, but keeping the line clean keeps both systems honest.
The supply chain planning system architecture, end to end
A supply chain planning system architecture has four layers: a data layer that ingests and stores the planning data, a planning engine that runs the forecasting and optimization, a scenario layer that holds versions and what-ifs, and a planner UI that people actually use. Each layer has one job and a clean boundary, and the discipline of keeping those boundaries honest is most of what separates a system that scales from one that buckles when the catalog doubles. This is the flagship view, so it is worth walking carefully.
Start at the bottom. The data layer ingests from the ERP, WMS, and OMS, cleans and conforms the master data, and stores the planning cube in a form the engine can read fast. For the volumes involved, that usually means a columnar or analytical store rather than a row-oriented transactional database, because planning queries sweep across huge ranges of cells. On top sits the planning engine, the compute core: the forecasting models, the constraint solver for supply planning, and the inventory math. This layer is where the heavy lifting happens, and it has to return answers in minutes, so it is typically built in performant Python and C++ libraries for the numerical work, scaled out across workers when the problem is large. Above the engine is the scenario layer, which manages plan versions, snapshots, and the what-if scenarios planners create, keeping them isolated so one person's experiment never corrupts the live plan. At the top is the planner UI, the grids, the exception alerts, the scenario comparisons, the place a human reviews machine output and applies judgment.
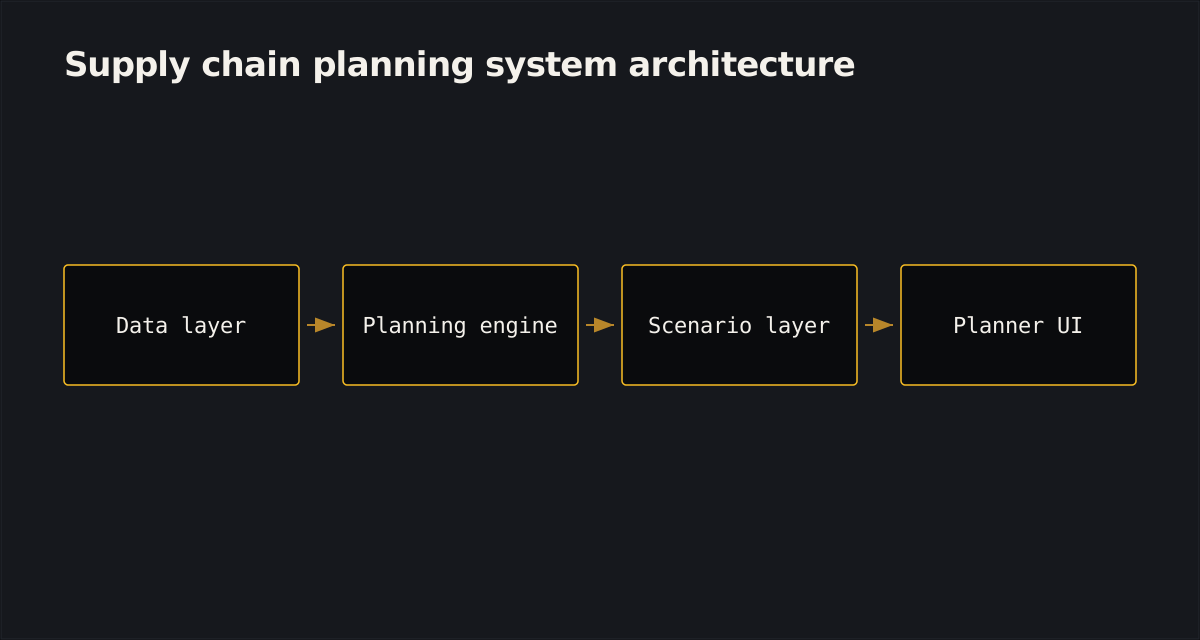
The reason to insist on these boundaries is change. The forecasting method will be swapped. The solver will be tuned. A new data source will land. When each layer is genuinely independent, those changes stay local instead of rippling through the whole system. That is ordinary good product development discipline applied to a numerically heavy domain, and it is exactly the kind of layered, data-grade system work behind the logistics platforms we build, from HaulBreeze to Conveya to Pikk-Up. The planner UI is the easy demo. The data layer and the engine are the build.
Build vs buy: when off-the-shelf supply chain planning is enough
The build-versus-buy decision for supply chain planning software comes down to one question: does your planning logic look like everyone else's, or is it the thing that makes you different. Packaged SCP suites exist for a reason, and naming a few in context is fair: vendors like Kinaxis, o9, Blue Yonder, and SAP IBP have spent years encoding standard planning processes into configurable products. When your planning maps onto what those suites assume, buying is the right call and building from scratch would be an expensive way to arrive at a worse version of what you could have configured.
Buy when the fit is good. If your product hierarchies are standard, your forecasting needs are conventional, and your S&OP process looks like the one the suite already models, a configured package is faster to stand up and cheaper to run over any realistic horizon. The vendor maintains the math and ships the upgrades, and you spend your engineering effort elsewhere. The honest builder's advice is that a great many companies are in exactly this position and should not be writing a forecasting engine.
Build, or more often go hybrid, when your planning logic is genuinely yours. A non-standard data model that no suite represents cleanly, a proprietary optimization that is a competitive edge, a workflow that does not fit any packaged process: these are the signals that custom or hybrid earns its cost. The common middle path keeps a packaged engine for the commodity math and builds custom services around the parts that are differentiated, integrated through clean APIs. Cost tracks that decision directly, configuring a suite, building a focused custom layer, and standing up a full custom platform sit at very different price points, and our supply chain software cost guide breaks down what actually moves the number. If you are weighing supply chain planning software against a custom build, that decision is best made against your real data and constraints. The logistics and supply chain team scopes exactly this trade-off, and our custom software development practice handles the build when custom is the answer.
Frequently asked questions
Supply chain planning decides what to make, buy, and stock before anything moves. It is the forecasting, balancing, and target-setting layer. Supply chain management is the broader discipline that also covers execution: running orders, warehouses, and transport once the plan is set. Planning is the brain that sets intent, management and execution are the hands that carry it out. Planning systems write targets, execution systems read and act on them.
Demand planning answers how much customers will buy, producing a statistical forecast by product, location, and time period. Supply planning answers how to meet that demand against real constraints: factory capacity, supplier lead times, and material availability. Demand planning is largely a forecasting problem solved with statistics and machine learning. Supply planning is largely a constraint problem solved with optimization. The demand plan is the input, the feasible supply plan is the output.
S&OP software supports sales and operations planning, the monthly process that reconciles the demand plan, the supply plan, and the financial plan into one agreed set of numbers. Following the framework that ASCM teaches, it pulls every function onto a shared dataset, runs scenarios when demand and supply disagree, tracks the gap to the financial target, and records the decisions. The output is one consensus plan that operations, sales, and finance all commit to, not three competing spreadsheets.
Accuracy depends on the product and the horizon, so it is measured rather than promised. Teams track error with MAPE or WMAPE and watch bias to catch consistent over or under forecasting. Fast-moving, stable products forecast well. New products, promotions, and long-tail items are harder, and no method removes that uncertainty. Good software does not chase a perfect number, it measures error honestly and feeds that variability straight into the safety-stock math so inventory absorbs what the forecast cannot.
Buy when your planning maps onto what a packaged suite assumes: standard hierarchies, conventional forecasting, and a process the vendor already models. A configured suite is faster and cheaper over any realistic horizon there. Build or go hybrid when your planning logic is the differentiator: a non-standard data model, proprietary optimization, or a workflow no suite fits. A common hybrid keeps a packaged engine for the commodity math and builds custom services for the parts that are genuinely yours.
Planning software sits on top of the transactional systems that hold the real data. It reads sales history and master data from the ERP, on-hand and in-transit stock from the warehouse system, and open orders from the order management system. After a plan is approved, it writes targets back: replenishment signals, production schedules, and inventory levels. Some feeds run as nightly batch, others stream closer to real time. Integration is usually the longest part of any planning build.
More from the journal

Demand Forecasting: Methods, Accuracy and Decisions
Demand forecasting predicts how much of each item sells, where and when. This covers the methods ladder from naive baselines to machine learning, the data each level needs, how accuracy is measured with MAPE, WAPE and bias, and how a forecast becomes an order.

AI in Supply Chain: Where It Works and What It Costs
Most AI in supply chain never leaves the pilot, and rarely because the model was wrong. Here is where it works across forecasting, inventory, routing, supplier risk, warehouses, asset health and documents, what data it needs first, and what a real build costs.
Order Management System: How It's Built
An order management system orchestrates an order from any channel to delivery. Here's the core services, the inventory and ATP logic, distributed order management, the EDI integrations, and what it takes to build.